gpt-crawler
22,413
Stars
2,344
Forks
133
Watchers
110
Open Issues
ISC
许可证
TypeScript
语言
2023-11-14
创建时间
2025-07-07
最近更新
项目能做什么
爬取指定网站生成知识库文件,方便快速构建基于自有网页的自定义 GPT。
来源:AI 基于仓库事实生成
· 内容以仓库实际 README 为准
使用说明 查看原始 README 原仓库文档
中文使用说明暂未生成。下面保留原仓库 README 摘录,命令与配置均以原文为准。
原始 README 摘录(英文原文,节选前 3000 字符)
# GPT Crawler <!-- omit from toc -->
<!-- Keep these links. Translations will automatically update with the README. -->
[Deutsch](https://www.readme-i18n.com/BuilderIO/gpt-crawler?lang=de) |
[Español](https://www.readme-i18n.com/BuilderIO/gpt-crawler?lang=es) |
[français](https://www.readme-i18n.com/BuilderIO/gpt-crawler?lang=fr) |
[日本語](https://www.readme-i18n.com/BuilderIO/gpt-crawler?lang=ja) |
[한국어](https://www.readme-i18n.com/BuilderIO/gpt-crawler?lang=ko) |
[Português](https://www.readme-i18n.com/BuilderIO/gpt-crawler?lang=pt) |
[Русский](https://www.readme-i18n.com/BuilderIO/gpt-crawler?lang=ru) |
[中文](https://www.readme-i18n.com/BuilderIO/gpt-crawler?lang=zh)
Crawl a site to generate knowledge files to create your own custom GPT from one or multiple URLs
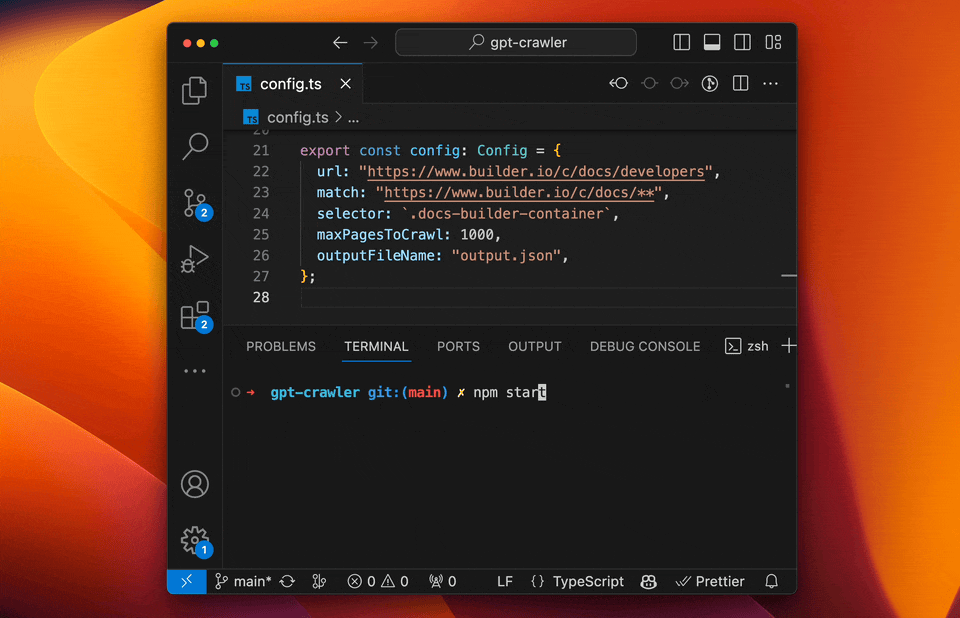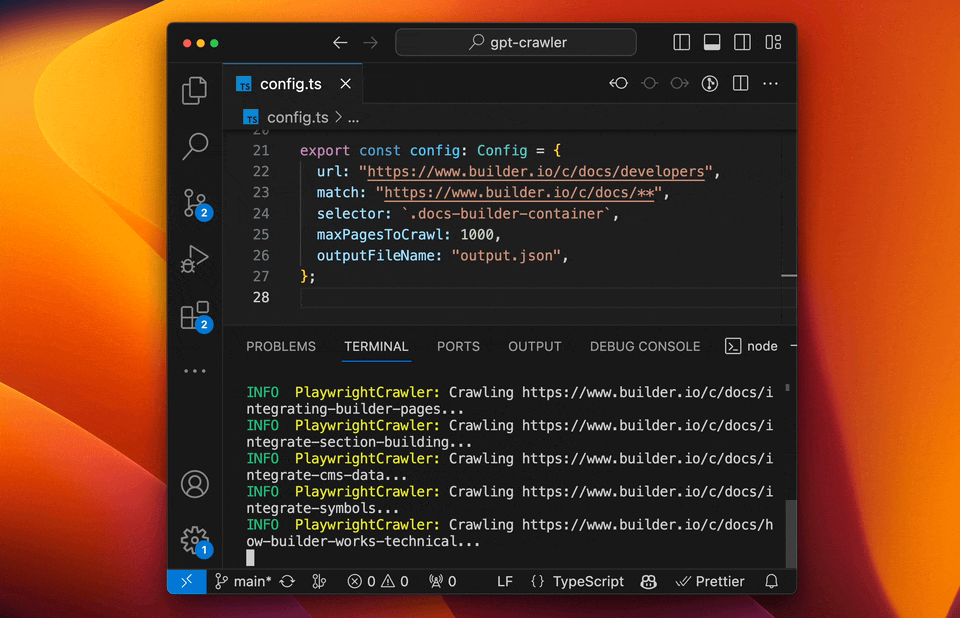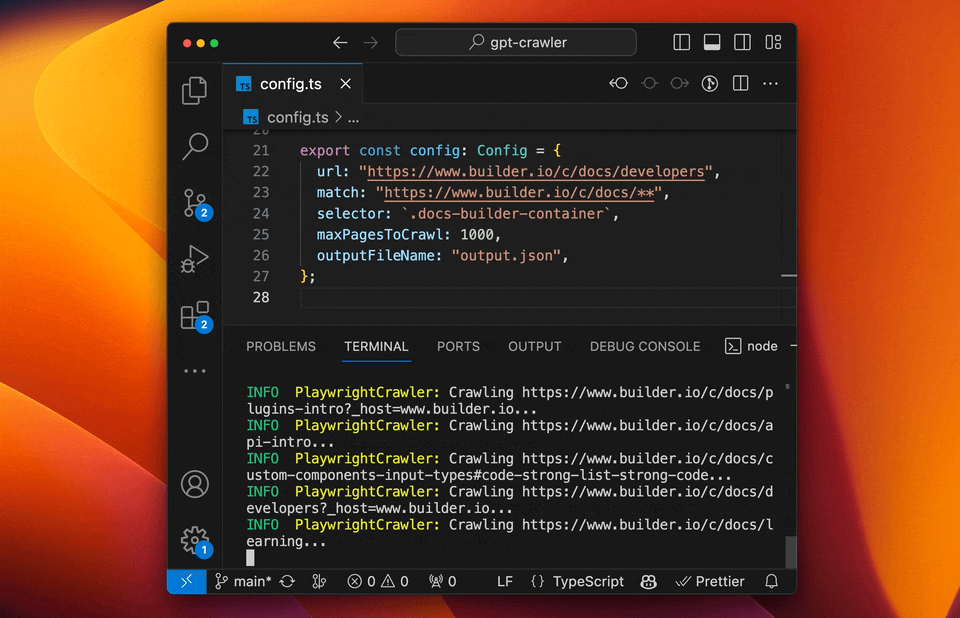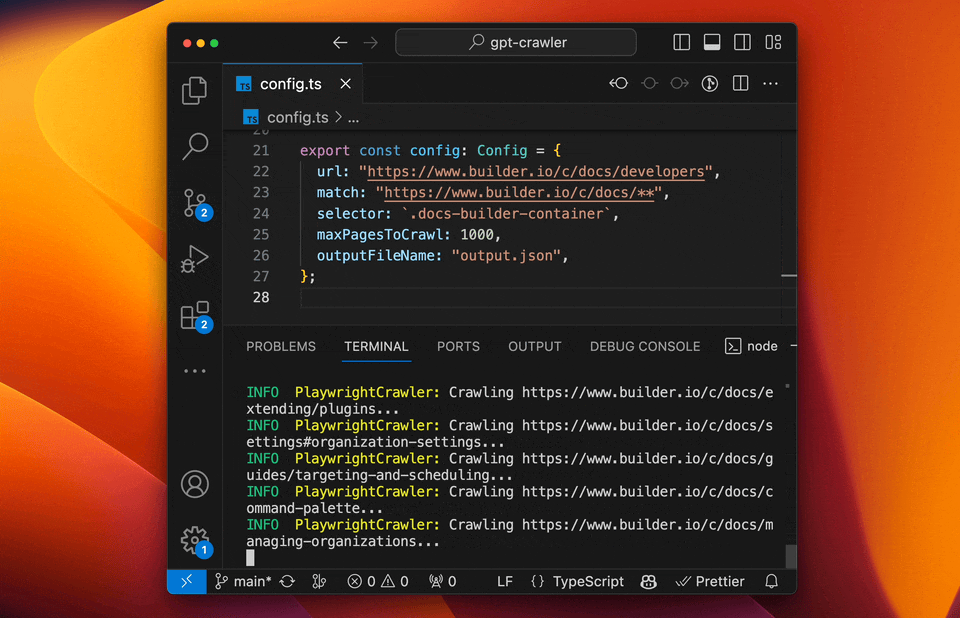
- [Example](#example)
- [Get started](#get-started)
- [Running locally](#running-locally)
- [Clone the repository](#clone-the-repository)
- [Install dependencies](#install-dependencies)
- [Configure the crawler](#configure-the-crawler)
- [Run your crawler](#run-your-crawler)
- [Alternative methods](#alternative-methods)
- [Running in a container with Docker](#running-in-a-container-with-docker)
- [Running as an API](#running-as-an-api)
- [Upload your data to OpenAI](#upload-your-data-to-openai)
- [Create a custom GPT](#create-a-custom-gpt)
- [Create a custom assistant](#create-a-custom-assistant)
- [Contributing](#contributing)
## Example
[Here is a custom GPT](https://chat.openai.com/g/g-kywiqipmR-builder-io-assistant) that I quickly made to help answer questions about how to use and integrate [Builder.io](https://www.builder.io) by simply providing the URL to the Builder docs.
This project crawled the docs and generated the file that I uploaded as the basis for the custom GPT.
[Try it out yourself](https://chat.openai.com/g/g-kywiqipmR-builder-io-assistant) by asking questions about how to integrate Builder.io into a site.
> Note that you may need a paid ChatGPT plan to access this feature
## Get started
### Running locally
#### Clone the repository
Be sure you have Node.js >= 16 installed.
```sh
git clone https://github.com/builderio/gpt-crawler
```
#### Install dependencies
```sh
npm i
```
#### Configure the crawler
Open [config.ts](config.ts) and edit the `url` and `selector` properties to match your needs.
E.g. to crawl the Builder.io docs to make our custom GPT you can use:
```ts
export const defaultConfig: Config = {
url: "https://www.builder.io/c/docs/developers",
match: "https://www.builder.io/c/docs/**",
selector: `.docs-builder-container`,
maxPagesToCrawl: 50,
outputFileName: "output.json",
};
```
See [config.ts](src/config.ts) for all available options. Here is a sample of the common configuration options:
```ts
type Config = {
/** URL to start the crawl, if sitemap is provided
阅读完整原文
项目深度分析 AI 生成
托管式 Web-to-GPT 知识库自动化云服务 (SaaS)
| 产品构想 | 将 gpt-crawler 封装为免本地环境配置的 Web 应用,用户输入目标网址与规则,云端自动爬取、分块、清洗,并一键推送到 OpenAI Assistant 或输出标准 JSON/Markdown。 |
| 核心功能 | 可视化的 CSS 选择器配置、定时自动重新抓取与增量更新、直连 OpenAI API 自动更新 Assistant 知识库文件、反爬与代理轮换支持 |
| 目标用户 | 非技术人员、中小企业产品运营、需要频繁更新 Custom GPT 知识库的创作者 |
| 难度/周期 | 中等 · 2-4 周 · 成本:轻量云服务器、无头浏览器集群资源(如 Browserless/Playwright 实例)、动态代理 IP 池费用 |
| 收费模式 | 免费额度 + 阶梯订阅制(按每月抓取页面数、抓取频率及同步知识库数量收费) |
| 竞争风险 | 目标站点反爬严格导致抓取失败率高;OpenAI 后续可能原生强化网页直接同步功能导致需求萎缩 |
| 依据 | 已验证事实 |
LLM 专用的高质量数据爬取与清洗 API (Developer API)
| 产品构想 | 对标 Firecrawl,提供专门面向 RAG 与大模型数据管道的 Scraping/Crawl API,输入 URL 直接返回结构化、去噪音的 Markdown 格式文本。 |
| 核心功能 | RESTful API 驱动、自动化处理 SPA/动态渲染、正文智能提取(无需手动写 CSS selector)、Markdown 格式清洗转换、Webhooks 结果通知 |
| 目标用户 | 构建企业级 RAG 应用的独立开发者、AI 初创团队、数据工程师 |
| 难度/周期 | 中等偏高 · 4-6 周 · 成本:高并发渲染服务器、代理 IP 带宽成本、基础后端架构成本 |
| 收费模式 | 按 API 调用量计费(按有效抓取页面数点卡或月度 API 套餐) |
| 竞争风险 | 市场上已有 Firecrawl、Jina Reader 等强力开源竞品,竞争较为激烈(AI推测) |
| 依据 | 数据支持的判断 |
企业私有化部署的文档知识库同步网关 (On-Premise / Enterprise Tool)
| 产品构想 | 针对企业内网文档、Confluence、Notion 或私有系统,提供内网爬取并格式化输出到本地向量库(如 Milvus、Qdrant)的容器化管理工具。 |
| 核心功能 | 支持 SSO 与私有鉴权(Cookie/Token 注入)、内网隔离部署、支持多种格式输出与向量数据库直接写入、敏感词脱敏清洗 |
| 目标用户 | 有数据合规要求、需要搭建内网知识库但缺乏爬虫管线的中大型企业 IT 部门 |
| 难度/周期 | 中等 · 3-5 周 · 成本:基础开发机与测试环境成本,极低运营成本 |
| 收费模式 | 软件买断授权费、技术支持与定制开发实施服务费 |
| 竞争风险 | 销售周期长,获客难度大(尚需验证的假设) |
| 依据 | 尚需验证的假设 |
AI 基于仓库公开数据分析生成,含推测成分,不构成收益承诺。
报告会保存到 个人中心
竞品与相似项目 GitHub Search 真实检索
相似项目数据正在完善中,暂不展示(避免误导)
项目优势与风险
| 技术成熟度 | 创建于 2023-11-14,最近推送 2025-07-07,发布过 8 个 Release |
| 社区活跃 | Star 22,413 / Fork 2,344 / Issue 110(数据支持,可自行核实) |
| 许可证 | ISC |
| 主要风险 | 上游项目方向可能变化;同赛道竞争者较多(见竞品表);热度与需求不完全等价 |
安装与使用
此项目未提供 Docker 镜像,安装步骤以原仓库 README 为准(涉及依赖安装与环境配置,对新手门槛较高)。